OPTIMIZING DATA LAKES FOR SCALABILITY: A STRATEGIC APPROACH
DOI:
https://doi.org/10.71465/csb45Keywords:
Data Lakes, Scalability, Data Storage, Data Processing, Predictive Analytics, Machine Learning, Distributed Systems, Cloud Computing, Big Data, PakistanAbstract
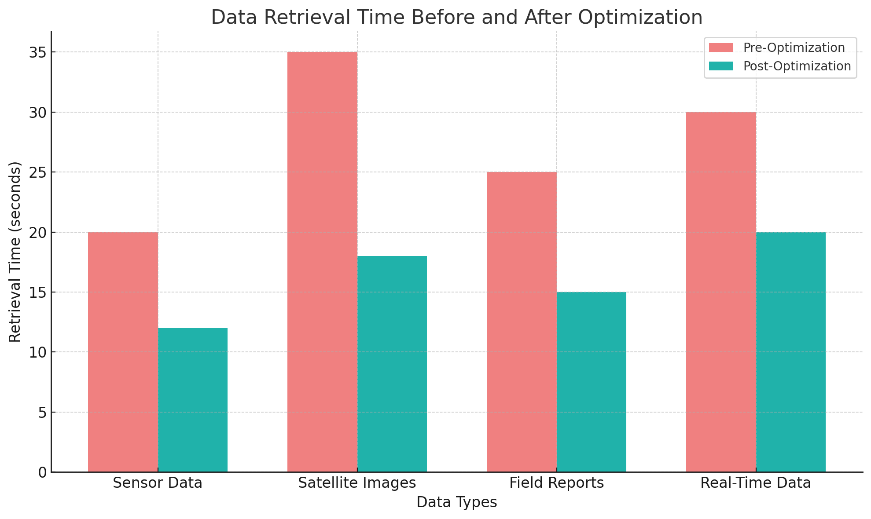
In recent years, data lakes have become a pivotal tool for managing vast amounts of unstructured and structured data. However, scalability remains a significant challenge when managing large-scale data lakes, particularly in terms of data storage, processing, and retrieval efficiency. This paper explores strategies for optimizing data lakes for scalability, focusing on both technological and organizational dimensions. We present a review of current techniques, including data partitioning, distributed architectures, and hybrid cloud integrations, and propose an innovative approach based on predictive analytics and machine learning to enhance scalability. The aim is to provide a comprehensive framework that will guide organizations in scaling their data lakes without compromising performance or data integrity. Furthermore, we assess the impact of these strategies through a case study involving a large-scale data lake deployment in Pakistan.
Downloads
Published
Issue
Section
License
Copyright (c) 2020 Dr. Ayesha Khalid

This work is licensed under a Creative Commons Attribution 4.0 International License.
All articles published in the Computer Science Bulletin are distributed under an open access license, allowing unrestricted use, distribution, and reproduction in any medium, provided the original work is properly cited. Authors retain copyright and grant the journal the right of first publication. The journal encourages knowledge sharing while maintaining academic integrity and proper attribution.