REAL-TIME ANALYTICS WITH APACHE KAFKA AND SPARK A COMPREHENSIVE OVERVIEW
DOI:
https://doi.org/10.71465/csb41Keywords:
Real-time Analytics, Apache Kafka, Apache Spark, Stream Processing, Big Data, Event Streaming, Data Pipelines, Data Processing, Latency, ScalabilityAbstract
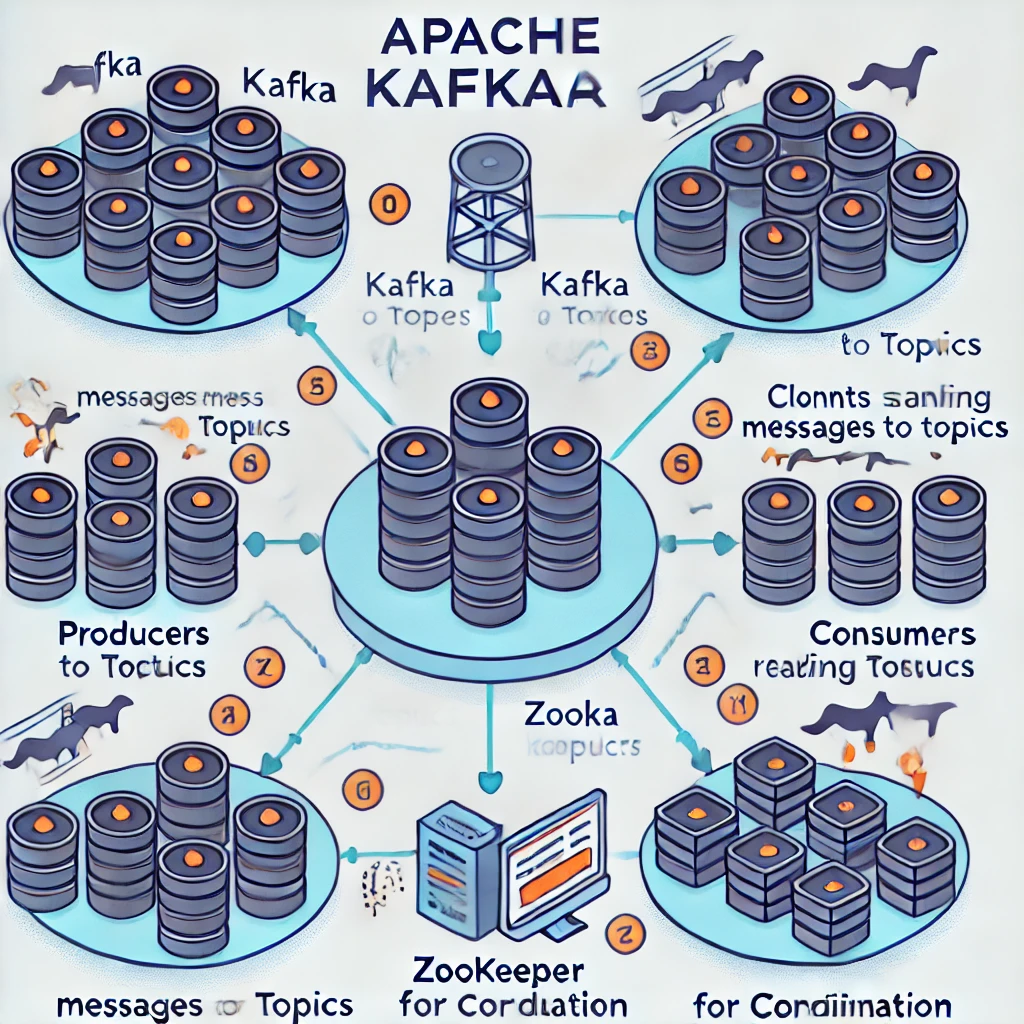
The increasing need for real-time data processing has led to the evolution of scalable and distributed systems capable of handling large volumes of data with low latency. Apache Kafka and Apache Spark are two key technologies that have emerged as industry standards for real-time analytics. Apache Kafka, a distributed event streaming platform, and Apache Spark, an in-memory data processing engine, together form a robust architecture for processing real-time data streams. This paper explores the integration of Apache Kafka and Spark for real-time analytics, focusing on their architecture, use cases, challenges, and performance optimization techniques. The study aims to provide a comprehensive understanding of how these technologies work together to enable real-time data pipelines, offering insights into their advantages, limitations, and potential future advancements in big data analytics.
Downloads
Published
Issue
Section
License
Copyright (c) 2020 Asma

This work is licensed under a Creative Commons Attribution 4.0 International License.
All articles published in the Computer Science Bulletin are distributed under an open access license, allowing unrestricted use, distribution, and reproduction in any medium, provided the original work is properly cited. Authors retain copyright and grant the journal the right of first publication. The journal encourages knowledge sharing while maintaining academic integrity and proper attribution.